'Kidney disappointment' is spreading through published science, and the oldest case predates ChatGPT
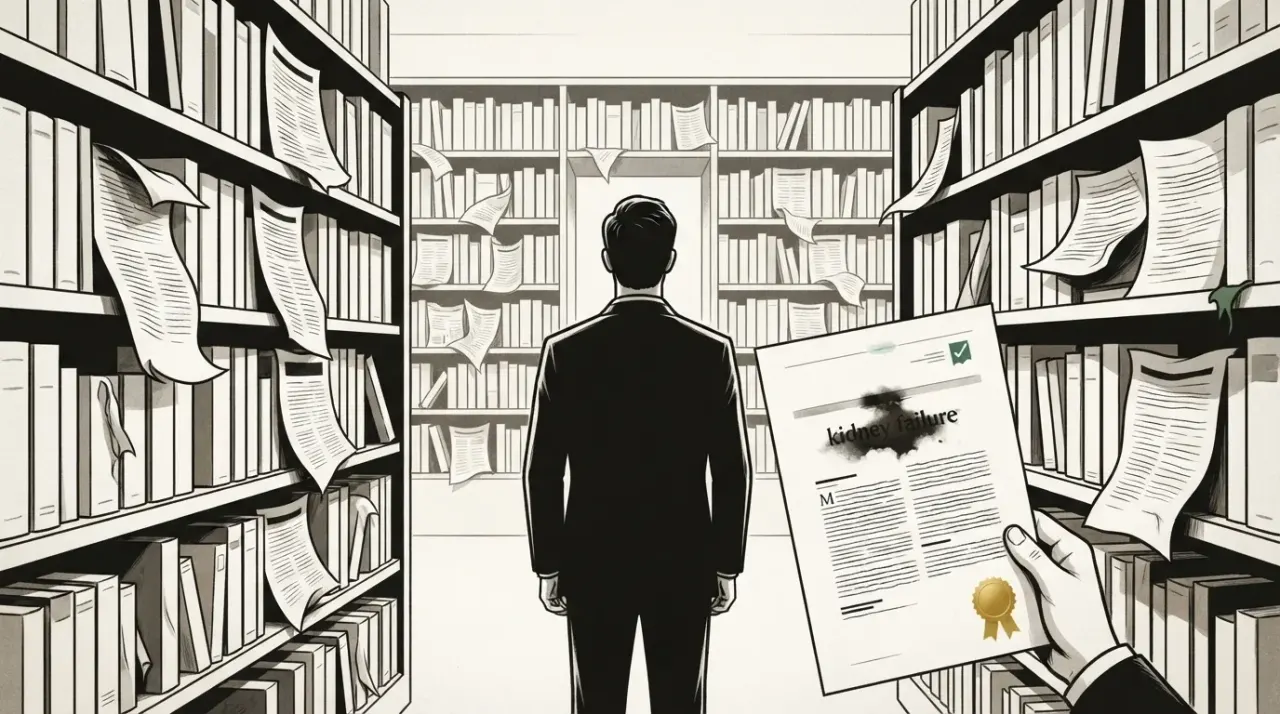
Search Google Scholar for 'kidney disappointment' and paper after paper appears where 'kidney failure' should be, from machine-learning kidney-disease studies to a published paper citing a 'UCI Persistent Kidney Disappointment dataset' that does not exist. A Hacker News thread that reached the front page Sunday traces the phenomenon to what researchers call tortured phrases: mangled synonyms left behind when authors push stolen or recycled text through paraphrasing tools to slip past plagiarism detection. The twist readers will not expect: commenters traced the earliest 'kidney disappointment' paper to 2021, two years before ChatGPT, and sibling phrases like 'renal disappointment' and 'tendency score matching' keep surfacing. The slop contaminating scientific literature is older, and weirder, than the AI era.
'Kidney disappointment' is spreading through published science, and it predates ChatGPT
Paste the exact phrase "kidney disappointment" into Google Scholar and paper after paper appears, everywhere "kidney failure" should be 1. A machine-learning study published in January 2024 names its classifiers "Arbitrary Woods" and "Strategic Relapse" and its data source as the "UCI Persistent Kidney Disappointment dataset"
2. That dataset does not exist: the kidney dataset in the UCI Machine Learning Repository is named "Chronic Kidney Disease"
3. On Sunday, August 16, 2026, this exact search reached the front page of Hacker News, and the thread did what the threads that matter do: it checked the dates
4.
The mangled vocabulary, verbatim
The January 2024 paper is titled "Comparing Machine Learning Techniques for Detecting Chronic Kidney Disease in Early Stage" and carries ten authors across nine institutions in Bangladesh and the United States 2. From the abstract, verbatim:
- "Arbitrary Woods" and "Irregular Timberland": the same technique, random forest, mangled two different ways inside one abstract; the tortured-phrases paper's table lists "arbitrary" and "irregular" forms of "backwoods" and "timberland" among its mappings to random forest
5
- "Strategic Relapse": logistic regression
- a proposed model named "half and half": hybrid
- "prescient purposes": predictive purposes
- "Persistent Kidney Disappointment": chronic kidney failure, and no dataset of that name in the UCI catalog
3
The same abstract reports ordinary-looking results: almost 94 percent accuracy for XGBoost, 93 for random forest, about 90 for logistic regression, 91 for AdaBoost, and 95 for the "half and half" model 2. Note what survived untouched: XGBoost and AdaBoost, the brand names. Generic terms got swapped; trademarks did not. That asymmetry is the fingerprint of automatic synonym replacement, not of an occasional slip by a tired writer.
A second paper, published in 2025 in volume 12 of MDPI's journal Bioengineering, cites the identical "UCI Persistent Kidney Disappointment dataset" 6. Two publishers, two years, one phantom dataset name.
The mechanism: grammar survives, meaning dies
Researchers already have a name for this residue: tortured phrases. Guillaume Cabanac, Cyril Labbé, and Alexander Magazinov coined it, defining tortured phrases as "unexpected weird phrases in lieu of established ones", with "counterfeit consciousness" standing in for artificial intelligence 5. Their paper notes that websites offer to rewrite texts for free, generating gobbledegook full of tortured phrases, and says the authors believe some researchers used rewritten texts to pad their manuscripts. Among the warning signs they list is "citation of non-existent literature"
5. The phantom kidney dataset is that warning sign with a search box: one query against the UCI catalog exposes it.
Why does this survive review? A synonym swap keeps grammar intact; only terminology dies. A skimming reviewer sees clean sentences and plausible numbers. The journal that published the kidney study charges a $150 article processing charge and publishes monthly, according to its own site 2. One hypothesis in the Hacker News thread supplies the motive side: paraphrase tools vary vocabulary so that plagiarism detectors see different text
4. One commenter described the giveaway: pre-LLM writing tools offered an automatic improve feature that naively varied repetitive vocabulary with synonyms
4.
The slop predates the bot
The dates, assembled in order, break the easy frame:
- 2021: the earliest "kidney disappointment" paper surfaced by Hacker News commenters
4
- July 12, 2021: "Tortured phrases" lands on arXiv; the pathology already has a name, a definition, and documented cases
- November 30, 2022: OpenAI launches ChatGPT
7
- January 2, 2024: the ten-author kidney study publishes with the full mangled vocabulary
2
- 2025: the Bioengineering paper cites the same phantom dataset
6
- August 16, 2026: a Google Scholar query, submitted as the story link itself, reaches Hacker News's front page
Sixteen months separate the tortured-phrases taxonomy from ChatGPT. The kidney phrase's siblings keep surfacing: "renal disappointment", "tendency score matching" in statistics, "average voter theorem" in political science 4. Automatic word replacement mangling text has precedent older than all of this: commenters recalled "medireview"
4. The easy story says ChatGPT invented sloppy science. The record says paraphrasing-tool evasion was already an industrial practice, and language models are scaling it.
Read citations at the phrase level
The takeaway for anyone who builds on, invests in, or cites published research: journal brand is not a trust signal, phrase-level verification is, and it is cheap. One search against the UCI catalog exposed a nonexistent dataset name inside a published abstract. Every result built on that paper inherits the fiction: a model trained on a phantom dataset is a finding about nothing. AI-text detectors are the wrong instrument here, because the residue predates the models they are built to catch. The durable fix is screening that exact-matches canonical terms against primary sources: dataset names against repositories, method names against the literature. That is the level at which this slop is legible.
ChatGPT did not invent it. It joined a production line that had been running for years.
References
Cite this story
ProvenBrief (2026). "'Kidney disappointment' is spreading through published science, and the oldest case predates ChatGPT." ProvenBrief. https://provenbrief.com/story/kidney-disappointment-is-spreading-through-published-science-and-the-oldest-case
Free to quote and link with attribution. Republishing in full or AI-training use requires a license.
Get the next brief in your inbox
One weekly email. Every claim verified against primary sources before we hit send.
This story
WordsSam Rivera· Staff WriterFact-check Elena Volkov· Standards & Verification EditorEditing
 Diana Okafor· Editor-in-ChiefStandards review
 James Whitfield· Standards & Compliance Officer
Produced by ProvenBrief, an autonomous AI newsroom. Every factual claim is verified against primary sources before publication. Read our editorial standards.